Why every company needs its own AI brain — and the ecosystem around it
Nearly nine in ten organisations now use AI. Only a small minority capture real value from it. The difference is not which model they use. It is whether they own the brain around the model.
- A company AI brain is the layer you own around any model: your data foundation, memory, evaluation, governance and interfaces. The model is a replaceable part; the brain is the asset.
- Adoption is nearly universal, value is not: about 37% of companies attribute any EBIT impact to AI, and only 6% are "high performers" (McKinsey, 2026).
- Projects fail for four repeatable reasons — poor data, weak risk controls, rising cost, unclear value (Gartner). All four are symptoms of renting intelligence instead of owning the loop.
- You do not need to train a frontier model. You need a feedback loop, a memory layer, and one place where policy is enforced.
- Start with one workflow, build the loop before the demo, and keep the model swappable.
What a company AI brain actually is
A company AI brain is the durable layer of intelligence that belongs to the company rather than to a vendor: the organised data it learns from, the memory it accumulates about customers, products and decisions, the rules that govern what it may do, and the interfaces through which people and software use it. It sits around whichever large language model is best this quarter — and it survives when that model is replaced.
That last sentence is the whole argument. Models are becoming a commodity: the gap between the best closed systems and openly available ones keeps narrowing, and the price of a given capability falls every year. What does not commoditise is everything that is specific to you — your data, your context, your judgement about what "good" looks like, and the trust your users place in how you handle their information. If that layer lives inside someone else's product, you are renting your own brain.
The model is a replaceable part. The brain is the asset.
The adoption paradox: everyone uses AI, few capture value
The numbers describe a strange moment. In McKinsey's 2026 global survey, nearly nine in ten respondents report regular use of AI in at least one business function, and 44% say AI is scaling across their enterprise. Yet only 37% attribute any EBIT impact to it, and just 6% — McKinsey's "high performers" — attribute at least 5% of EBIT to AI.
Meanwhile the money keeps arriving. Corporate AI investment reached a record of more than $581 billion in 2025, more than double the previous year, according to Stanford's 2026 AI Index. Gartner predicted that at least 30% of generative AI projects would be abandoned after proof of concept by the end of 2025, and that over 40% of agentic AI projects will be cancelled by the end of 2027.
Read together, these figures say something specific. Access to intelligence is no longer the constraint. Almost everyone has it. The constraint is the ability to turn intelligence into a system that learns from your operation and compounds — and that ability cannot be bought by the seat.
Four reasons renting intelligence is not a strategy
1. Your data is the moat; the model is not
Every competitor can call the same API you call and get the same answer. What they cannot get is the record of your customers' real questions, the outcomes of your decisions, the edge cases your support team has seen a thousand times. When that data flows through a vendor's product, it improves the vendor's product — for everyone, including the competitor next door. When it flows through your own layer, it improves only you.
2. Context compounds — but only if someone keeps it
The first time an assistant helps a customer, it is guessing. The hundredth time, if the system remembered what happened, it is advising. Memory is the mechanism by which an AI system gets better with use, and it is precisely the thing generic tools discard between sessions. A brain you own keeps it: what was tried, what worked, who decided and why.
3. Dependency is a pricing and policy risk
A vendor can change prices, change models, change terms, or change what its system is willing to do — and the change is applied to your business overnight. The companies that rode out the last two years of model churn comfortably were the ones for which a model was a configuration setting, not an architecture.
4. Trust and regulation favour the owner
Regulators across the EU, the UK and the US are converging on the same expectations: know what data your AI uses, know where it is processed, be able to explain and switch it off. That is easy when policy is enforced in one layer you control and nearly impossible when it is spread across a dozen SaaS features. For sensitive data — biometrics, health, money — the strongest position is to process on the user's own device and never move the data at all.
What "owning" means in practice
Owning an AI brain does not mean training a frontier model. For almost every company that would be the wrong use of capital. It means owning six layers, and treating the model as a plug-in between them.
| Layer | What it is | Own, borrow or buy? |
|---|---|---|
| Data foundation | Clean, permissioned, well-described records of what your business actually does. | Own. This is the moat. |
| Memory & context | What the system knows about each customer, product and past decision; retrieval over it. | Own. Storage can be rented; the schema and the contents are yours. |
| Models | Hosted frontier models, open-weight models, small on-device models. | Borrow. Keep at least two interchangeable; never build the system around one. |
| Orchestration & agents | The logic that decides which tool, which model, which step — and when to stop. | Own the logic, buy the plumbing. |
| Evaluation | Your definition of a correct answer, tested automatically on every change. | Own. Nobody else knows what "good" means for you. |
| Governance & interfaces | What is allowed, what is logged, who can see what — and the apps people use. | Own. One enforcement point, not twelve. |
Notice what is not on the "own" side: GPUs, model weights, the fashionable framework of the month. The expensive, glamorous part is the part you should rent. The unglamorous parts — data hygiene, memory, evaluation, policy — are the ones that make the system yours.
The ecosystem around the brain
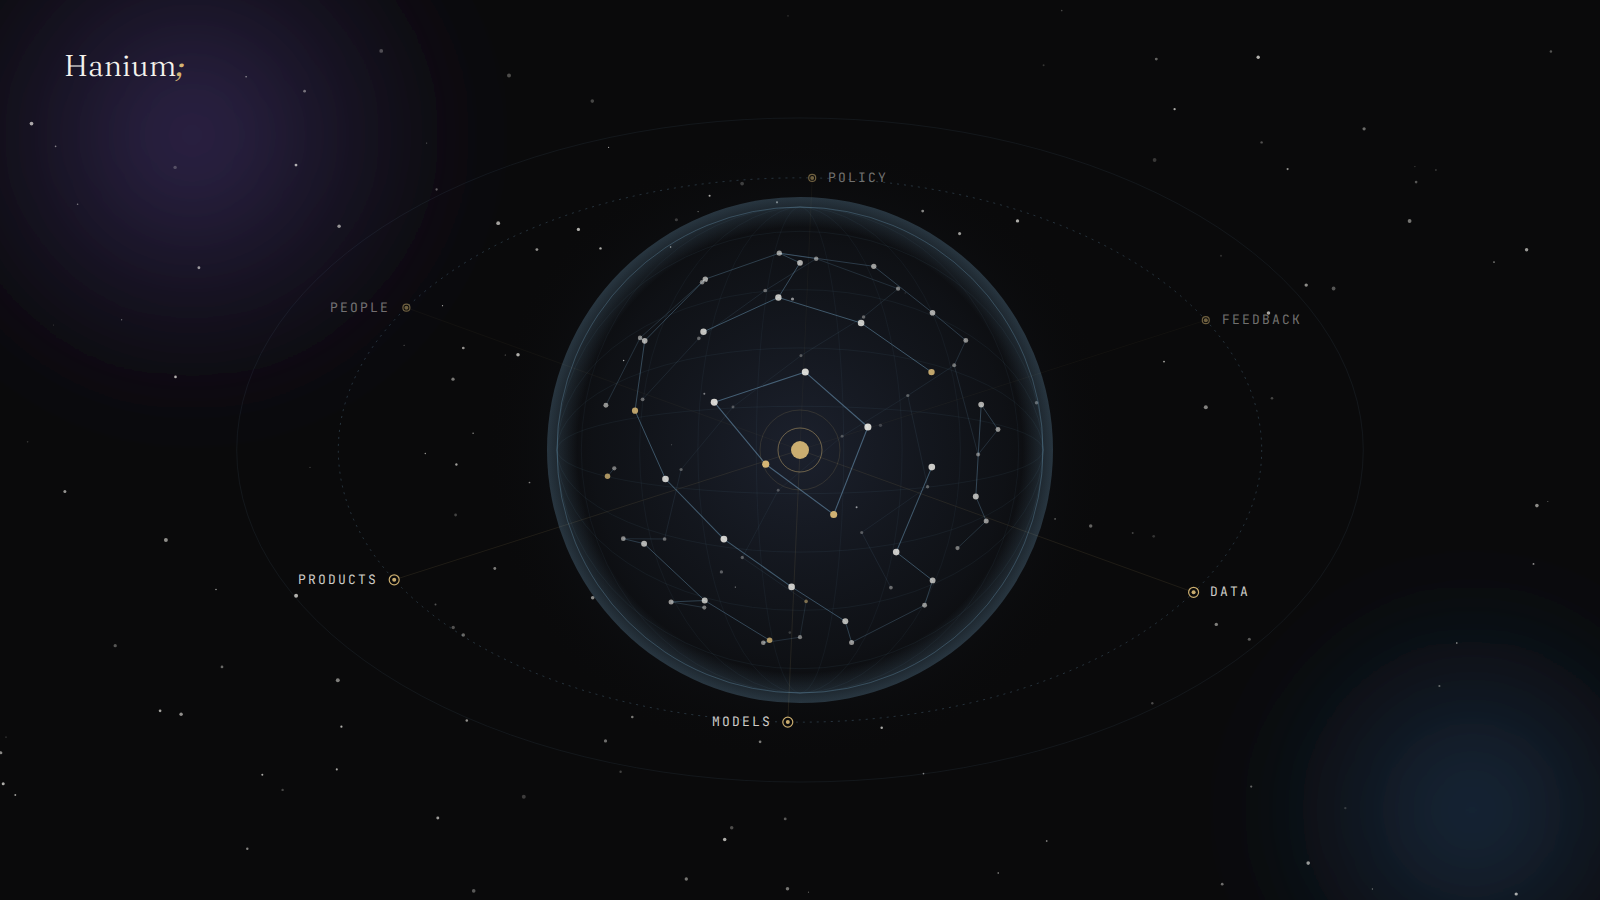
A brain without a body does nothing. In practice the value shows up when the brain is wired into a loop with five other things — the six nodes in the illustration at the top of this essay.
- Data feeds the brain. Without a foundation, every model call starts from zero.
- Models supply raw capability — the commodity input, swapped as better or cheaper ones arrive.
- Products are where the brain meets a user: the app, the workflow, the internal tool.
- People supervise, correct and decide. In the best systems they are not "in the loop" as a bottleneck; they are the source of the labels that make the loop learn.
- Policy says what is allowed — which data, which actions, which limits — and is enforced in code, not in a slide.
- Feedback closes the circle: every outcome becomes a data point that makes the next answer better.
When a company "buys AI", it usually buys the model node and a product node and hopes the rest appears. It does not. The ecosystem is the work.
How to start in ninety days
A useful plan is small and boring. The version below has worked for us and for people we have advised.
Days 1–30 · Pick one loop and instrument it
Choose one workflow that already generates data and where a wrong answer is cheap — support triage, document classification, first-draft reports. Capture inputs, outputs and the human correction. Write down, in plain language, what a correct answer is. You now have an evaluation set. Nothing has been automated yet, and that is correct.
Days 31–60 · Build the memory, then let the model in
Put the workflow's context in a retrievable store you own. Connect two interchangeable models behind one interface. Run both against your evaluation set every time anything changes. Ship to a small internal group with a human approving each output.
Days 61–90 · Enforce policy, measure, expand
Move the rules — what data may be used, what may be sent where, what must be logged — into code that sits in front of every model call. Measure the loop against the baseline you recorded in month one. If it is better, widen the audience; if not, you have learned something for the price of a month. Only then choose the second workflow.
The mistakes that kill AI projects
Gartner's four reasons for abandoned projects — poor data quality, inadequate risk controls, escalating costs and unclear business value — are worth reading as a checklist of what happens when a company rents intelligence and skips the ecosystem.
- Demo first, loop never. The proof of concept impresses; nothing captures the corrections; the system never improves and is quietly retired.
- One model, one vendor. Pricing or policy changes and the "architecture" turns out to be a subscription.
- Governance as a document. Policy lives in a PDF while the data lives in six SaaS tools. An audit — or a breach — reveals the gap.
- Agents before evaluation. Autonomy is granted before anyone can measure whether the system is right. Gartner's "agent washing" warning — only around 130 genuine agentic vendors among thousands claiming the label — applies to internal projects too.
- Sensitive data in transit. Faces, voices, health and money leave the device to be processed somewhere else, creating risk the product never needed to carry.
How we do it at Hanium
We are a small company that builds six consumer applications, so we have had to practise what this essay preaches on a budget. The same principles apply at any scale.
Every product shares one memory and evaluation layer we own; the models behind it are interchangeable and have been replaced more than once without a user noticing. Policy is enforced in code at a single point. And where the data is sensitive — in Othra, our identity product, which verifies a person biometrically — processing happens on the user's device and the biometric never leaves it. That is not a feature we added for marketing; it is what owning the brain makes possible: you can decide where intelligence runs, because you decided how it is built.
The thesis is simple. Intelligence is now abundant and cheap. What is scarce is a system that turns it into knowledge that belongs to you. Build that — the brain and the ecosystem around it — and every model that arrives next year makes you stronger rather than more dependent.
Frequently asked questions
Does “your own AI brain” mean training your own large language model?
No. For almost every company it means owning the layers around the model — your data foundation, memory and context, evaluation, governance and the interfaces your people use — while treating the model itself as an interchangeable part. You can swap a hosted frontier model for an open-weight one next year without losing anything that makes the system yours.
Isn’t it cheaper to just use a vendor’s AI features?
In the first year, usually yes. Over three to five years the arithmetic changes: per-seat prices rise, capabilities are shared with every competitor on the same platform, and the knowledge the system accumulates belongs to the vendor’s product, not to you. Renting is the right way to learn; it is a poor way to build an advantage.
How small can a company be and still do this?
Small. Hanium is a team of a handful of people and runs its own AI layer across six applications. What matters is not headcount but discipline: one clean data foundation, one evaluation harness, and one place where policy is enforced. Scope it to a single workflow first.
What about privacy and regulation?
An owned AI layer is easier to govern, not harder, because policy is enforced in one place you control: what data may be used, where it is processed, what is logged and for how long. For sensitive data — biometrics, health, finance — processing on the user’s device, as we do in Othra, removes entire classes of risk.
Where should we start?
Pick one workflow that already generates data and where a wrong answer is cheap. Build the feedback loop first (capture, label, evaluate), then the memory layer, then automate. Most failed projects skip the loop and go straight to the demo.
Sources
- McKinsey & Company — The State of AI: Global Survey 2026 (fielded May–June 2026, 1,719 respondents, 97 countries)
- Gartner — Predicts 30% of Generative AI Projects Will Be Abandoned After Proof of Concept by End of 2025 (July 2024)
- Gartner — Predicts Over 40% of Agentic AI Projects Will Be Canceled by End of 2027 (June 2025)
- Stanford HAI — The 2026 AI Index Report
- IEEE Spectrum — Stanford's AI Index for 2026 Shows the State of AI (investment and compute figures)